Getting Started
nexus-dev-toolkit gives your team a repeatable AI-assisted workflow in two distinct phases: Day 0 — a one-time production-grade project boilerplate, run once by one person — and Day 1 — the daily EPAV loop every developer runs for every feature, for the life of the project.
/scaffold once, before anyone
starts feature work. Individual developers should never run /scaffold during Day 1: doing so
re-scaffolds the project. Once Day 0 is done, every developer works exclusively in Day 1, forever.
Overview
Once your project is set up, this is what you'll run every day:
/evaluate <task> → /plan → /apply → /validate → /code-reviewOne task from your dev tasks CSV, four EPAV steps plus a code review, repeat forever. Full Day 1 walkthrough ↓
/code-review isn't one of the four EPAV phases — it's a separate reviewer skill — but it's the
recommended last step before calling a task done. 4 more reviewer skills (database, deployment, performance,
monitoring) are also available any time — see built-in skills.Autonomous loop — apply ↔ validate can retry itself without a human cranking every turn. See the loop guide.
Setup
$ curl -LsSf https://astral.sh/uv/install.sh | sh$ npm install -g @anthropic-ai/claude-code
$ claude loginWith graphify: scoped subgraph queries — fast, accurate, low token cost. Auto-updates after every file edit via the PostToolUse hook.
Without graphify: EPAV skills still work but fall back to full file reads — slower, more token-heavy, and blast radius analysis is best-effort only.
$ uv tool install graphifyy
$ graphify install # registers /graphify skill into Claude Codenexus doctor warns if it
finds graphs from both built in the same project.$ npm i -g @colbymchenry/codegraph
$ codegraph install # wires codegraph into Claude Code / OpenCode / etc.$ uv tool install nexus-dev-toolkitnexus init
Run once inside your project folder. All nexus commands operate on the current directory by
default — .claude/, knowledge/, and .mcp.json are created relative to where
you run them.
cd into your project first, then run nexus init . — the dot means "here".
$ cd my-project
$ nexus init . # Claude Code (default)
$ nexus init . --tool opencode # OpenCode
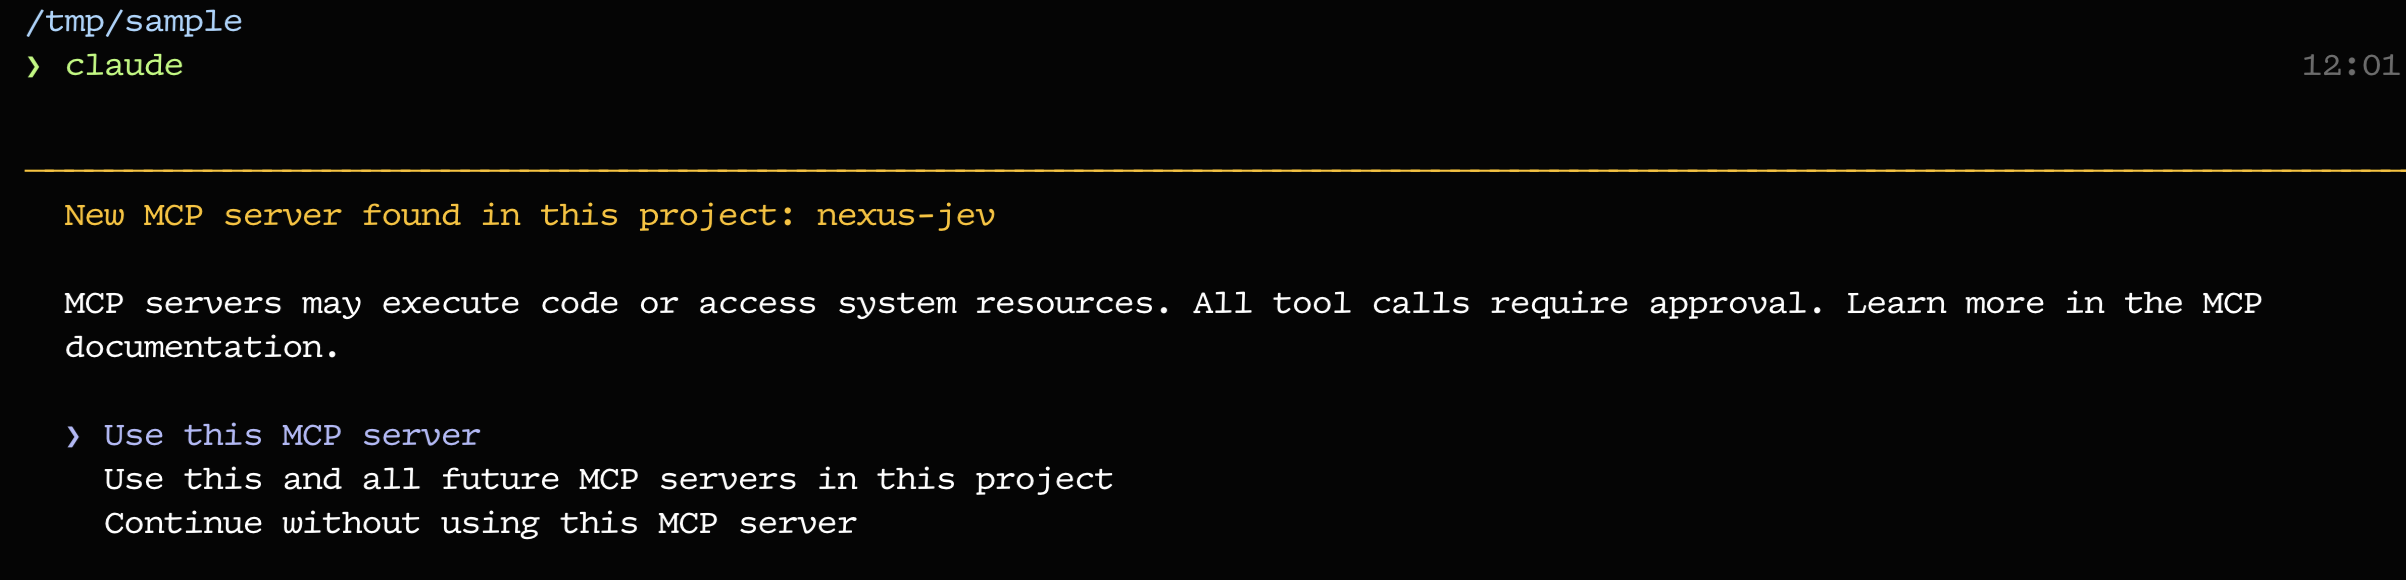
$ nexus init . --tool codex # CodexUse this MCP server (or
Use this and all future MCP servers in this project). Picking
Continue without using this MCP server means none of the EPAV tools
(ingest_architecture_doc, resolve_package_versions, etc.) will actually
be available during that session, even though .mcp.json is configured correctly.
Claude Code (default)
.claude/
├── commands/
│   ├── scaffold.md          ← /scaffold         — Day 0 setup
│   ├── evaluate.md          ← /evaluate         — orient on task
│   ├── plan.md              ← /plan             — blueprint
│   ├── apply.md             ← /apply            — implement
│   ├── validate.md          ← /validate         — verify
│   ├── epav.md              ← /epav             — full cycle guide
│   ├── code-review.md       ← /code-review      — reviewer skill
│   ├── database-review.md   ← /database-review  — reviewer skill
│   ├── deployment-review.md ← /deployment-review
│   ├── performance-review.md← /performance-review
│   ├── monitoring-review.md ← /monitoring-review
│   ├── commit.md             ← /commit           — stage & commit
│   ├── create-pr.md          ← /create-pr        — open a PR
│   ├── pr-review.md          ← /pr-review        — deep-verify a commit/PR
│   └── dev-tasks-planner.md  ← /dev-tasks-planner — generate dev-tasks CSVs
├── agents/
│   ├── code-reviewer.md
│   ├── database-reviewer.md
│   ├── deployment-reviewer.md
│   ├── performance-reviewer.md
│   ├── monitoring-reviewer.md
│   └── pr-verifier.md
└── settings.json            ← PostToolUse: graphify auto-update hook (graphify backend only)
knowledge/
├── rules/                   ← coding standards, arch decisions
├── patterns/                ← reusable implementation patterns
├── prompts/dev/             ← task prompt templates
└── retros/                  ← retrospective notes
docs/                        ← arch-docs/, dev-tasks/, designs/, requirements/
.mcp.json                    ← MCP server config
OpenCode
tools, model) are stripped on copy. The graphify plugin fires on every tool execution
via tool.execute.after — only scaffolded if you picked graphify at nexus init's
--graph-backend prompt. Pick codegraph instead and nothing is scaffolded here; codegraph wires
and syncs itself via codegraph install && codegraph init.
.opencode/
├── commands/
│   ├── scaffold.md          ← /scaffold         — Day 0 setup
│   ├── evaluate.md          ← /evaluate         — orient on task
│   ├── plan.md              ← /plan             — blueprint
│   ├── apply.md             ← /apply            — implement
│   ├── validate.md          ← /validate         — verify
│   ├── epav.md              ← /epav             — full cycle guide
│   ├── code-review.md       ← /code-review      — reviewer skill
│   ├── database-review.md   ← /database-review  — reviewer skill
│   ├── deployment-review.md ← /deployment-review
│   ├── performance-review.md← /performance-review
│   ├── monitoring-review.md ← /monitoring-review
│   ├── commit.md             ← /commit           — stage & commit
│   ├── create-pr.md          ← /create-pr        — open a PR
│   ├── pr-review.md          ← /pr-review        — deep-verify a commit/PR
│   └── dev-tasks-planner.md  ← /dev-tasks-planner — generate dev-tasks CSVs
├── agents/
│   ├── code-reviewer.md
│   ├── database-reviewer.md
│   ├── deployment-reviewer.md
│   ├── performance-reviewer.md
│   ├── monitoring-reviewer.md
│   └── pr-verifier.md
└── plugins/
│   └── graphify.js          ← tool.execute.after: graphify auto-update (graphify backend only)
knowledge/
├── rules/
├── patterns/
├── prompts/dev/
└── retros/
docs/                        ← arch-docs/, dev-tasks/, designs/, requirements/
opencode.json                ← MCP server config
Codex
.agents/skills/<name>/SKILL.md — invoke them with $evaluate, $plan, … or /skills.
The EPAV steps also get agents/openai.yaml with allow_implicit_invocation: false, so Codex never starts
$apply or $commit on its own. Agents are converted to Codex TOML (Claude Code-only tools/model are dropped;
they inherit your session model). The nexus MCP block is appended to .codex/config.toml — existing config is never rewritten.
Codex only loads project .codex/ config and hooks for trusted projects — trust it when asked.
.agents/skills/
├── evaluate/
│   ├── SKILL.md             ← $evaluate — orient on task
│   └── agents/openai.yaml   ← explicit-only (EPAV steps)
├── plan/ apply/ validate/ epav/ scaffold/ commit/ create-pr/ dev-tasks-planner/
└── code-review/ database-review/ … pr-review/   ← reviewer skills (implicit allowed)
.codex/
├── agents/
│   ├── code-reviewer.toml
│   └── …                    ← all 6 reviewer subagents
├── config.toml              ← [mcp_servers.nexus]
└── hooks.json               ← PostToolUse: graphify auto-update (graphify backend only)
knowledge/                   ← same structure
docs/                        ← arch-docs/, dev-tasks/, designs/, requirements/
The docs/ folder
docs/ is where your project's reference material lives — the documents Claude reads to understand
what you're building and how. nexus init creates the four folders below for every tool (Claude Code,
OpenCode, Codex). It only creates folders: if docs/ already exists, nothing inside it is moved,
renamed or overwritten, and re-running nexus init just adds any folder that's missing.
docs/
├── arch-docs/       ← HOW: architecture doc, ADRs
├── dev-tasks/       ← WHAT TO DO NEXT: task CSVs, one row per task
├── designs/         ← WHAT IT LOOKS LIKE: design exports (e.g. Figma ZIP)
└── requirements/ ← WHAT & WHY: BRD, PRD, user stories| Folder | Put here | Read by |
|---|---|---|
arch-docs/ |
Your architecture document and ADRs, as markdown. Stack, data model, auth, error format, security rules. | ingest_architecture_doc (scans this folder by default), /scaffold, /evaluate, /dev-tasks-planner |
dev-tasks/ |
Task CSVs with columns task_id, user_story, description, acceptance_criteria, dependencies. Usually one file per module or epic. |
load_task (scans this folder by default), /evaluate. Written by /dev-tasks-planner. |
designs/ |
Design exports — a Figma export ZIP, screens, a design-system spec. | /scaffold (design system + UI shell), /dev-tasks-planner |
requirements/ |
Business and product requirements: BRD, PRD, user stories, acceptance notes. | No step loads it automatically yet — point Claude at it (e.g. /evaluate a task "per docs/requirements/prd.md") when requirements matter. |
ingest_architecture_doc scans
all of docs/arch-docs/ and extracts stack, data model and security rules from whatever it finds. A PRD
dropped in there would be parsed as architecture and pollute those results. Requirements answer what and why;
architecture answers how — keep them apart.
nexus init . themselves.
Day 0 — /scaffold (one-time, reference)
Run once per project, by one person — usually the tech lead — before anyone starts feature work. Never re-run during Day 1. Produces a production-grade scaffold from your architecture document and Figma design. No business logic, no live integrations — mock auth, mock data, zero external dependencies.
/scaffold, not /evaluate — it runs the same
Evaluate → Plan → Apply → Validate shape as Day 1, just once, kicked off from your architecture doc instead of
a task description.
Prerequisites
docs/nexus init already created the folders. For Day 0 you need at least your architecture doc in
docs/arch-docs/ and your design export in docs/designs/. See
The docs/ folder for what goes where and which step reads it.
nexus init ..claude/commands/, knowledge/, and
.mcp.json.
/scaffold/scaffold/graphify . # if you chose graphify at init
$ codegraph install && codegraph init # if you chose codegraph, run in your terminalnexus doctor any time to check which backend is active./scaffold runs EVALUATE first, then stops and waits. You review and type the next
command to continue. The flow is:/scaffold → (review) → /plan → (review) → /apply → (review) →
/validate
What happens inside each of those four phases — EVALUATE, PLAN, APPLY, VALIDATE:
EVALUATE (via /scaffold, not typed separately)
Claude summarises 10 key decisions from your arch doc and Figma before writing a single line of code:
| # | Question |
|---|---|
| 1 | Stack decisions and why |
| 2 | Data model — tables, relationships, indexes |
| 3 | Infrastructure needed from day one |
| 4 | Middleware + auth flow |
| 5 | Error response format |
| 6 | Security rules and constraints |
| 7 | Design tokens — Figma oklch/hex → hsl() for web, Color() for Flutter |
| 8 | Component inventory — every component, variants, states |
| 9 | Layout patterns — grid, breakpoints, responsive |
| 10 | Iconography — library, sizes, style |
Claude stops. Review the summary, then type /plan to continue.
PLAN (type /plan)
Blueprint only — no code. Four outputs:
| Output | Contents |
|---|---|
| Infrastructure | Directory structure, schema, env vars, auth flow, error handler |
| UI shell | Component list, props interfaces, page layouts, build order |
| AGENTS.md | Project rules for all AI tools — coding standards, git conventions, quality gates |
| knowledge/ | Coding standards, patterns, prompt templates, design system spec |
Claude stops. Review the blueprint, then type /apply to generate code.
APPLY (type /apply)
First step — always: Claude calls resolve_package_versions before writing any file.
Exact versions from the real package manager lock file — never from AI memory.
// MCP tool — call this first
resolve_package_versions({
packages: ["next@16", "react@19", "@supabase/supabase-js@2"],
stack_hint: "Next.js 16 TypeScript"
})
// → { "versions": { "next": "16.3.2", "react": "19.1.0", ... } }Then generates everything in one scaffold:
| Category | Files |
|---|---|
| Config | .gitignore, .env.example, ESLint, Prettier, TypeScript |
| Auth (mock) | Login sets mock-role cookie (8h). No credentials checked. Route guard reads cookie. |
| Infrastructure | Schema migration, error handler, health check, seed script |
| Git hooks | Husky + lint-staged + commitlint. chmod +x .husky/pre-commit. HUSKY=0 for CI.
|
| CI | GitHub Actions: lint, typecheck, test, build |
| Design system | Tailwind config, globals.css (hsl() tokens — never oklch), font loading |
| Components | All components with every visual state — default, hover, focus, disabled, loading, empty, error |
| Pages | All pages responsive at 320/768/1024/1440px with mock data |
| Project rules | AGENTS.md, knowledge/rules/coding-standards.md |
resolve_package_versions. Never use npx create-next-app or any scaffold CLI.
VALIDATE (type /validate)
Build must pass first, then Claude runs a 19-point checklist:
| Category | Checks |
|---|---|
| Packages (4) | Stable versions, no deprecated APIs, lock file pinned, no CVEs |
| Infrastructure (6) | Structure matches arch, schema matches data model, env vars documented, production logging, security headers, DB pooling |
| UI fidelity (6) | Matches Figma, responsive at 4 breakpoints, all visual states, WCAG AA, props typed for Day 1, no API calls in components |
| AGENTS.md + knowledge (2) | Coding standards match arch, design system spec saved |
| Git hooks (1) | Pre-commit hook configured and executable |
Every [BLOCKER] and [FIX NOW] must be fixed before Day 0 is called complete.
Success: npm install && npm run dev works. Zero credentials needed.
Day 1 — EPAV (the daily loop)
The same commands from the top of this page, in full, one phase at a time. One task from the dev tasks CSV. Four EPAV steps plus a code review. Repeat forever.
/evaluate <task> → /plan → /apply → /validate → /code-reviewWant apply ↔ validate to retry itself automatically instead of waiting on a human each turn? See the autonomous loop guide.
/evaluate
Orient on the task before touching any code.
graphify query or codegraph explore, whichever backend is
active. Find all files the task touches. Map the blast radius — what else references those
files./plan
Blueprint only — no code written.
graphify path, or codegraph impact as the closest available
check (it takes one symbol, not a file pair). Confirm relationships between primary files. State what else
will be affected./apply
Implement exactly what the plan says. No scope creep.
| Day 1 replaces | With |
|---|---|
| Mock data in components | Real DB client calls |
| Mock auth cookie | Real auth provider |
| Placeholder Route Handlers | Validated API handlers with error handling |
| Schema file | Applied migration + RLS policies |
graphify auto-updates after every file edit — via the PostToolUse hook in .claude/settings.json
(Claude Code) or the tool.execute.after plugin in .opencode/plugins/graphify.js
(OpenCode) or the PostToolUse hook in .codex/hooks.json (Codex). All are installed automatically by nexus init if you picked graphify. codegraph
updates itself via its own background sync daemon — no hook needed, and none is scaffolded.
/validate
npm run build / flutter build apk /
go build ./... — fix all errors before continuing.
[PASS] / [FAIL] /
[PARTIAL]
[BLOCKER] and [FIX NOW] must be resolved before the task is
done. [BACKLOG] items go to knowledge/retros/.knowledge/patterns/./code-review
Run once VALIDATE passes, before calling the task done. Not one of the four EPAV phases — a separate reviewer skill — but the recommended last step on every task. See built-in skills for the full reviewer list (database, deployment, performance, monitoring).
MCP Server Setup
MCP tools power the graph queries and task-loading calls used throughout /evaluate and /apply above — set this
up once, alongside install. nexus init writes .mcp.json automatically. For Claude
Desktop, add manually:
Claude Code (project-level)
// .mcp.json
{
"mcpServers": {
"nexus": {
"command": "uvx",
"args": ["--refresh", "--from", "nexus-dev-toolkit", "nexus-mcp"]
}
}
}Claude Desktop (macOS)
// ~/Library/Application Support/Claude/claude_desktop_config.json
{
"mcpServers": {
"nexus": {
"command": "uvx",
"args": ["--refresh", "--from", "nexus-dev-toolkit", "nexus-mcp"]
}
}
}OpenCode (project-level)
nexus init . --tool opencode writes opencode.json automatically. To add manually:
// opencode.json
{
"$schema": "https://opencode.ai/config.json",
"mcp": {
"nexus-mcp": {
"type": "local",
"command": ["uvx", "--refresh", "--from", "nexus-dev-toolkit", "nexus-mcp"]
}
}
}Codex (project-level)
nexus init . --tool codex appends this to .codex/config.toml automatically (trusted projects only). To add manually:
# .codex/config.toml
[mcp_servers.nexus]
command = "uvx"
args = ["--refresh", "--from", "nexus-dev-toolkit", "nexus-mcp"]MCP Tool Reference
| Tool | Purpose | When to call |
|---|---|---|
ingest_architecture_doc |
Extract arch doc sections → knowledge/rules/arch-summary.md |
Day 0, Step 2 — before /scaffold |
load_task |
Load a CSV task row + knowledge-graph blast radius into context | Day 1, start of /evaluate |
generate_project_rules |
Generate AGENTS.md + knowledge/ structure from arch doc | Day 0 PLAN — before writing files |
resolve_package_versions |
Run real package manager in temp dir → exact pinned versions | Day 0 APPLY — must be first step |
Built-in Skills
The full list behind every command used so far — plus the reviewer skills, which aren't part of any EPAV phase and run on their own.
| Skill | Trigger | Phase |
|---|---|---|
| EPAV Workflow | ||
scaffold.md |
/scaffold |
Day 0 — one-time setup |
evaluate.md |
/evaluate |
Day 1 — orient on task |
plan.md |
/plan |
Day 1 — blueprint |
apply.md |
/apply |
Day 1 — implement |
validate.md |
/validate |
Day 1 — verify |
epav.md |
/epav |
Day 1 — full cycle guide |
| Reviewers | ||
code-review.md |
/code-review |
Review code quality, bugs, security |
database-review.md |
/database-review |
Review schema, migrations, queries |
deployment-review.md |
/deployment-review |
Review CI/CD, Docker, infra config |
performance-review.md |
/performance-review |
Review performance and bottlenecks |
monitoring-review.md |
/monitoring-review |
Review observability and alerting |
| Git | ||
commit.md |
/commit |
Stage relevant changes and create a well-formed commit |
create-pr.md |
/create-pr |
Run /code-review, then open a well-structured pull request |
pr-review.md |
/pr-review |
Deep-verify a specific commit/PR by SHA or URL against its own claims |
| Planning | ||
dev-tasks-planner.md |
/dev-tasks-planner |
Generate or reconcile docs/dev-tasks/*.csv files from an architecture doc + real repo state |
Built-in Agents
Subagents copied to .claude/agents/ on nexus init. Claude Code can spawn them
automatically based on context, or you can ask Claude to use one directly.
| Agent | Triggers when |
|---|---|
code-reviewer |
Code quality review, best practices, maintainability |
database-reviewer |
Schema changes, migrations, query optimization |
deployment-reviewer |
CI/CD pipelines, Docker, infrastructure config |
performance-reviewer |
Performance bottlenecks, caching, resource usage |
monitoring-reviewer |
Observability gaps, logging, metrics, alerting |
pr-verifier |
Deep-verifying a specific commit/PR by SHA or URL against its own claims, with a real build/test run |
/code-review) you invoke manually, and as
agents (code-reviewer) Claude can spawn automatically. Both are installed by
nexus init.
Custom Skills
$ nexus skill add my-reviewCreates .claude/commands/my-review.md with a starter template. Edit it, then type
/my-review in Claude Code. For OpenCode, manually copy the file to .opencode/commands/.
# .claude/commands/code-review.md

# /code-review

**code-review** — review the current diff for correctness, security, and style.

## Steps

### 1 — Load context
Run graphify query on changed files. Check knowledge/rules/ for relevant standards.

### 2 — Review
Check: correctness, security, performance, style, test coverage.

### 3 — Output
Findings grouped by severity: [BLOCKER] / [FIX NOW] / [BACKLOG]
Rules
$ nexus rule add api-standardsCreates knowledge/rules/api-standards.md. Skills reference rules via knowledge/ — the
AI reads them during EVALUATE and APPLY to enforce project standards.
All Commands
| Command | Description |
|---|---|
| Project Setup | |
nexus init [dir] |
Initialize for Claude Code (default) |
nexus init [dir] --tool opencode |
Initialize for OpenCode |
nexus init [dir] --tool codex |
Initialize for Codex |
nexus update |
Update the nexus CLI itself to latest — does not touch any project's .claude/.opencode files. In a real terminal, asks whether to also sync the current directory; scripted/CI runs skip the prompt automatically |
nexus update --sync |
Same as above, but skips the prompt and always syncs the current directory's skills/agents (skipped if it isn't a nexus project) |
nexus sync [dir] |
Sync built-in skills & agents to latest versions (custom files untouched) |
nexus doctor [dir] |
Validate project setup — checks tools, skills, agents, MCP config, knowledge graph (graphify/codegraph) |
nexus --version |
Show installed version |
| Skills | |
nexus skill list |
List all skills in .claude/commands/ |
nexus skill add <name> |
Create a custom skill |
| Agents | |
nexus agent list |
List all subagents in .claude/agents/ |
nexus agent add <name> |
Create a custom subagent |
| Rules | |
nexus rule list |
List all rules in knowledge/rules/ |
nexus rule add <name> |
Create a project rule |
knowledge/ Layout
knowledge/
├── rules/
│   ├── arch-summary.md      ← generated by ingest_architecture_doc
│   └── coding-standards.md  ← generated by generate_project_rules
├── patterns/
│   └── implement-and-test.md ← E→P→A→V pattern
├── prompts/dev/             ← task prompt templates
└── retros/                  ← [BACKLOG] items from /validate
nexus-jev — Experimental TypeSafe/Jev Build
nexus-dev-toolkit — different name, different commands (nexus-jev /
nexus-jev-mcp), its own release history on PyPI. Installing it never touches your
existing nexus install.
Replaces a handful of hardcoded keyword-matching heuristics in the EPAV tools with an actual AI judgment call via TypeSafe's Jev model — which architecture-doc section is about auth vs. security, which of ~30 stack tags an arch doc mentions, which package manager or IaC tool fits a free-text hint, which CSV column means "acceptance criteria," which design-token name maps to which role. Every tool works exactly the same without it: TypeSafe is off by default, and every judgment falls back to the original heuristic if it isn't enabled or the API call fails.
Also adds support for infrastructure-shaped projects: project_shape (web_app /
mobile_app / backend_api / infrastructure / data_pipeline / cli_or_library) and
has_infrastructure_component, so /scaffold can generate
Terraform/OpenTofu, Helm, or Ansible deliverables instead of — or alongside — application
boilerplate.
Install
$ uv tool install nexus-dev-toolkit-jevInstalls nexus-jev and nexus-jev-mcp as real, separate commands — run them
side by side with nexus / nexus-mcp on the same machine, no conflict.
Usage
$ cd my-project
$ nexus-jev init . --typesafe # prompts if --typesafe/--no-typesafe omittedUse this MCP server (or
Use this and all future MCP servers in this project). Picking
Continue without using this MCP server means none of the EPAV tools
(ingest_architecture_doc, resolve_package_versions, etc.) will actually
be available, even though .mcp.json is configured correctly — this applies to the
regular nexus MCP server the same way, not just nexus-jev.
Enabling TypeSafe needs one more step: set a TYPESAFE_API_KEY (get one at
console.typesafe.ai).
Without it, every tool below falls back to its original heuristic automatically — nothing breaks,
you just don't get the smarter detection.
$ export TYPESAFE_API_KEY=your-key-here
$ nexus-jev doctor # reports whether TypeSafe is wired up and the key is set| Tool | TypeSafe-powered judgment |
|---|---|
ingest_architecture_doc |
Which category a doc section belongs to; project_shape /
has_infrastructure_component |
generate_project_rules |
Which of ~30 stack tags an arch doc mentions (Next.js, Django, Terraform/OpenTofu, Kubernetes, ...) |
resolve_package_versions |
Which package manager or IaC tool (npm/pnpm/yarn/pub/go/cargo/maven/gradle/pip, Terraform/OpenTofu, Helm, Ansible) fits a free-text stack hint |
load_task |
Which canonical task field a CSV column maps to, regardless of header naming |
ingest_design_export (new) |
Which design-token role a CSS custom property plays (primary, error, spacing, ...) — accepts a Figma export or a standalone HTML mockup (e.g. from Claude's Design artifact type) |
Full write-up — including the Terraform/OpenTofu/Helm/Ansible support
and version-resolution mechanics — lives in the repo:
experimental-jev branch and its tools/README.md.